Compositional AI: Beyond Familiar Combinations
Recognizing familiar ingredients is easier than understanding a new arrangement. Compositional generalization tests whether a model can make that jump.
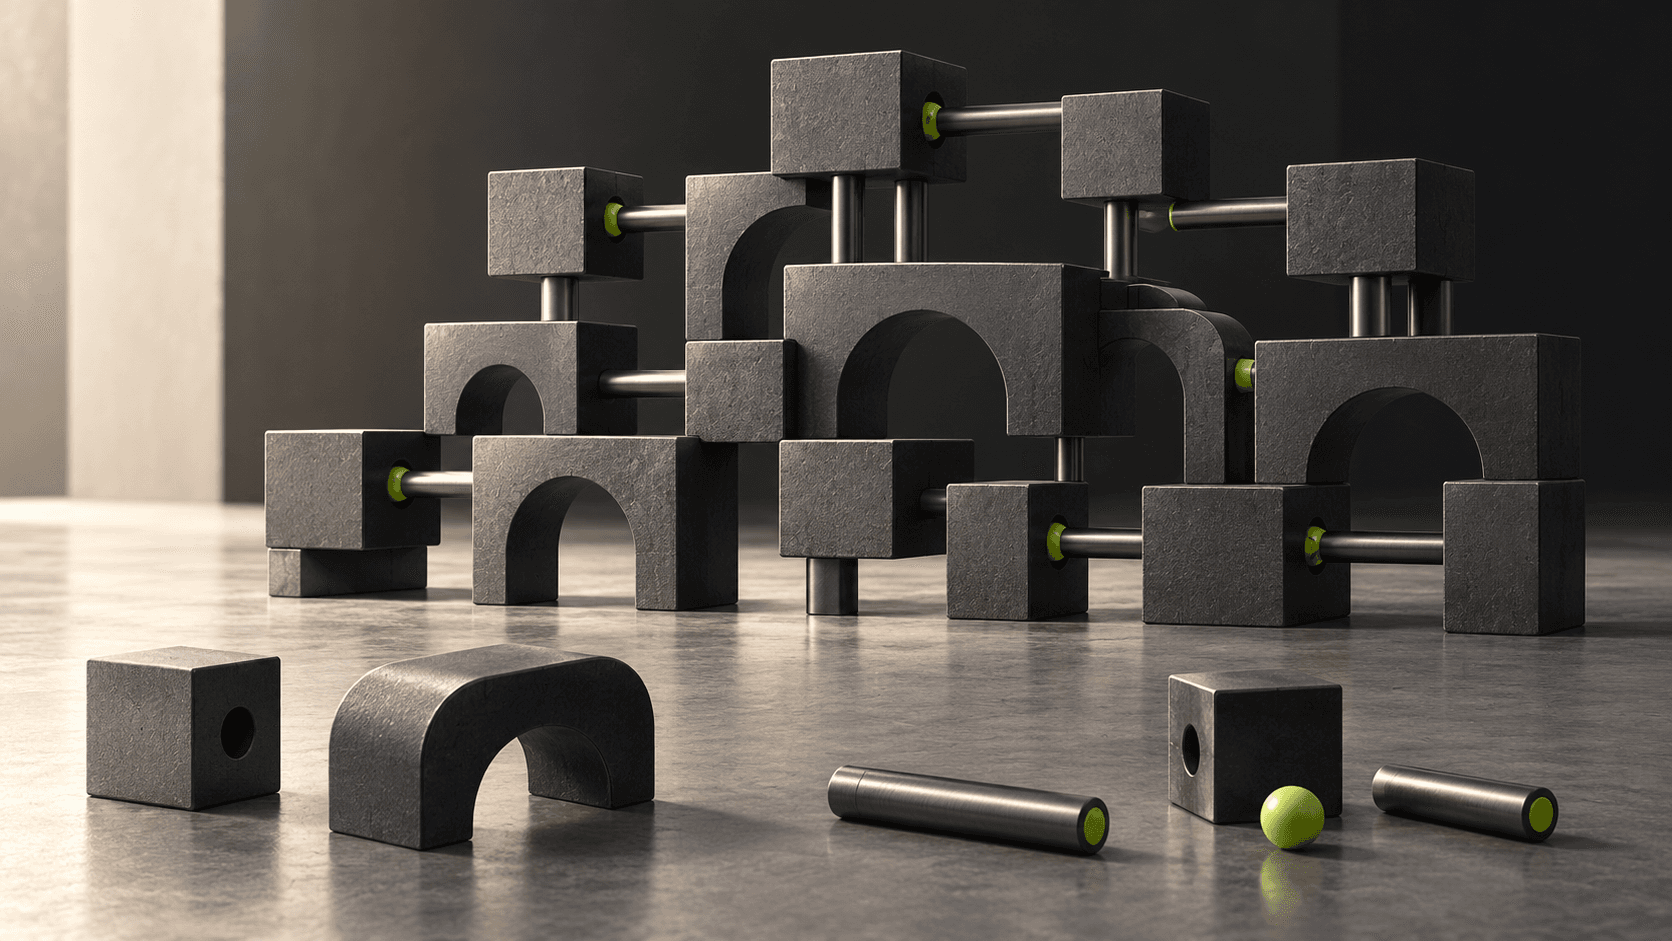
A model may recognize a red object and understand the instruction "place the object behind the box," yet fail when the red object appears in an unfamiliar arrangement. Knowing the ingredients does not necessarily mean knowing how to combine them.
Compositional generalization is the ability to handle new combinations of familiar components, attributes, operations, or relationships. It matters wherever the space of possible situations is larger than the training set: language, robotics, visual reasoning, software workflows, and industrial monitoring.
Two meanings that should stay separate
Compositional AI sometimes describes modular software assembled from specialist models and tools. It also describes a learning objective: systematic generalization to combinations not observed during training. A modular application does not automatically possess the second property.
For example, connecting an object detector to a planner creates a pipeline. Whether that pipeline can understand a new relationship between known objects is a separate empirical question. The word composition should identify the property being claimed, not substitute for a test.
Why a random test split is not enough
Imagine a dataset of machine observations labeled by operating mode and fault type. A random split may place examples of every mode-fault pairing in both training and test sets. Strong test performance then shows performance on new examples of familiar combinations.
A compositional evaluation deliberately withholds selected combinations while retaining their individual ingredients elsewhere in training. A model might see a certain fault in one operating mode and the second mode under other conditions, then face their held-out pairing at test time.
This split must still be physically meaningful. Withholding a combination that cannot occur, or allowing correlated samples from the same run to cross the split, produces a different problem. The evaluation design needs domain knowledge as well as a random seed.
What recent research suggests
The ICML 2025 paper Does Data Scaling Lead to Visual Compositional Generalization? studies controlled visual tasks and reports that diversity and coverage of combinations matter beyond simply increasing dataset size. That finding supports a careful data-design question: which combinations does additional data actually add? It does not prove that scaling is irrelevant in every domain.
A 2026 PMLR workshop paper on representational homomorphism error investigates whether internal representations preserve compositional operations. Its controlled experiments use SCAN-style tasks and small Transformers. The interesting direction is a diagnostic connection between representation structure and generalization; it should not be treated as a universal predictor for all language models.
Together, these studies suggest looking beyond one aggregate benchmark score. A system may succeed through dataset-specific correlations while failing to preserve the relationships needed for a new composition.
Structure can help, but it must earn its complexity
Useful design options include object-centered representations, explicit relations, typed intermediate outputs, reusable modules, and architectures aligned with the operations in a task. None provides compositional generalization by its name alone.
An explicit parser or executor can make some combinations easier to inspect. A learned representation can reduce brittle hand-written rules. A hybrid approach can combine both. The appropriate choice depends on whether the domain's structure is known, whether perception is noisy, and whether intermediate errors can be supervised.
Start with the smallest architecture that permits a meaningful comparison. If a larger system improves only familiar combinations, it may have increased capacity without improving the property that motivated the work.
A practical evaluation plan
Create a matrix of components and combinations before training. Mark what is seen, what is held out, and which environmental factors vary independently. Keep a conventional test set so the cost of improved compositional performance remains visible.
- Report performance separately on familiar and held-out combinations.
- Distinguish unfamiliar combinations from unfamiliar individual concepts.
- Test longer compositions and changed relationships, not just new surface wording.
- Inspect failure by component, relationship, and composition length.
- Compare against simpler models and shortcuts that exploit superficial correlations.
The objective is not to claim that a model can generalize to every arrangement. It is to define a useful family of rearrangements and demonstrate what transfers. That makes compositional AI a concrete research program rather than an optimistic description of modular software.
Sources and further reading
- Does Data Scaling Lead to Visual Compositional Generalization?, ICML 2025
- Representational Homomorphism Error Predicts Compositional Generalization in Language Models, PMLR 2026 workshop proceedings
Research perspective. Sources checked on 20 October 2026; proposed industrial examples describe evaluation designs, not completed experiments.